
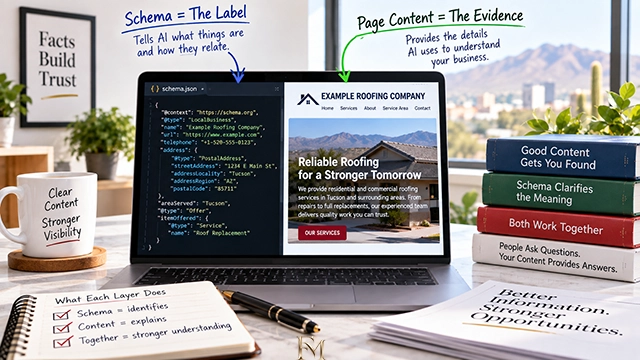
Schema vs Page Content
If you are deciding whether the next round of budget goes into schema markup or into rewriting your pages, here is the direct answer. AI systems read both, but not for the same purpose. Your page content is the evidence. Your schema is the label attached to it. When ChatGPT, Claude, or Gemini describes your business, nearly everything in that description traces back to content, meaning sentences somebody wrote, on your site and on sites you do not own. Schema does a narrower job. It states which business those sentences belong to, what kind of thing each item is, and how the pieces relate to each other.
So the two are not substitutes, and the comparison only becomes useful when you turn it into a different question: which of the two is failing you right now? Both can be technically correct while the answers AI gives about your business are still wrong, and each layer fails in a way you can learn to recognize from the answer itself.
Why They Get Framed as Competitors
Nobody would compare a filing cabinet to the documents inside it. Schema and content end up on opposite sides of a decision because both get sold with the same sentence: this will help AI understand your business. That makes them look like two routes to one destination, and once they look interchangeable, they compete for the same money.
Schema usually wins that competition, because a markup project has an ending. It validates, the ticket closes, and somebody can point at a screen and confirm the work is done. Rewriting a services page has no such moment. It is slower, it requires deciding what the business actually is, and the result is prose rather than a passing test. So the spend goes to the layer that can be verified, and the layer that carries the meaning gets deferred.
What Each Layer Is Actually Made Of
Content is claims in sentences. Your services page says you replace flat commercial roofs in the Phoenix metro. A supplier page says the same thing in different words. A review describes a job you did. Every one of those is a small piece of evidence, and AI weighs them together, which is how AI builds a picture of your business from information across the web. Because models take your words literally, the specificity of those sentences sets the ceiling on how specifically you can be described.
Schema is declarations. It states this is the organization, this is its category, this is its address, this is a service it offers, this article belongs to that organization. As covered in What Schema Actually Does, it does not introduce information. It removes the step where AI has to work out what your sentences meant.
Notice the difference in scale. Your markup is one small block per page. Your content is every page you have published, plus every page anyone else published that mentions you. One is a label on a file. The other is the file.
Only One of Them Travels
Here is the part that rarely gets said, and it decides more than the technical arguments do. Content moves. A clear sentence on your site gets paraphrased into a directory listing, quoted in an article, echoed by a partner, restated in a review by a customer who read it. Over a few years, a single well written description of what you do can appear, reworded, in dozens of places. That matters because repetition across independent sources is one of the strongest signals AI has, and it is the main thing that makes AI confident in an answer.
Markup does not move. Nobody republishes your structured data. No directory copies your Organization block. It is read where it sits and nowhere else, which is the practical meaning of the boundary described in Schema Stops at the Edge of Your Website. Your markup can only ever speak on the one property you control, while the conversation AI is actually listening to happens across hundreds you do not.
What the Evidence Currently Shows
This is an area where the marketing has run ahead of the findings, so it is worth being precise.
A 2026 analysis by Ahrefs tracked roughly 1,900 pages that added structured data over a seven month period against a matched set of pages that did not. Across Google AI Overviews, AI Mode, and ChatGPT, the pages that added markup showed no meaningful lift in citations. The researchers noted a real limit on that finding: every page studied was already cited heavily, so the test measured whether markup pushes a visible page higher, not whether it helps an invisible one get parsed at all.
A separate test came at it from the other direction. A researcher published a page for a business that did not exist and placed its address only inside a markup block, in a form that was not even valid. ChatGPT and Perplexity both repeated the address on request. The lesson is not that broken markup works. It is that the models read that block as text sitting on the page, not as a verified record with special standing.
Meanwhile Microsoft has stated publicly that structured data helps its models understand web content, and Google engineers have described it as making their generative systems run more reliably.
Put those together and the picture resolves. Schema does its heaviest work upstream, inside the search indexes and knowledge graphs that feed AI answers, where it is parsed properly and used to establish identity. When a model reads your page directly, your markup is simply more words competing with the rest of the words. In neither pipeline is schema the source of the substance. It is what keeps the substance from being misfiled.
How to Tell Which Layer Is Failing
Ask AI about your business and the shape of the answer points at the layer.
Right business, empty description. The model names you correctly, places you in the right industry, and then says nothing a competitor could not also claim. Phrases like “appears to offer” and “a range of services” are the tell, and What AI Uncertainty Looks Like When It Describes a Business covers the rest of them. This is a content problem. There was nothing specific to extract, and markup cannot manufacture a specific claim that the writing never made. Clear writing beats clever writing precisely here.
Confident description, wrong subject. The answer is specific and fluent, and some of it belongs to somebody else. A namesake’s reviews, a competitor’s price range, a category next to yours rather than yours. That is an identity and classification failure, the pattern behind Entity Confusion Between Similar Businesses and behind Why AI May Recognize Your Business but Misunderstand Its Specialty. Content alone will not fix it, because the problem is not what was said but where it got filed. This is schema’s home ground, which is the point of How Schema Supports Entity Recognition and Organization Schema Explained.
Specific, accurate, and years out of date. Neither layer on your site is the cause. The evidence off your site still describes the business you used to be, and both your markup and your rewritten pages are outvoted by volume.
Which One Deserves the Money First
For most businesses, content comes first, because most businesses do not have an identity problem. They have a substance problem, and adding labels to vague copy produces clearly labeled vagueness. That is the argument made at length in Schema Does Not Override Bad Content, and it is the usual case.
The exception is worth taking seriously. If your name is common or shared, if you operate several locations, if you changed your name, or if your service lines blur into each other, your problem is identification rather than description. Prose cannot solve that reliably, however well written it is. A paragraph mentioning your city is a phrase to interpret. Markup stating your exact legal name, address, and confirmed profiles elsewhere is a declaration. That is why unique business names help and why markup matters more after a name change than at any other moment in a company’s life.
The Cost of Guessing Wrong
Spending on the wrong layer does not produce an error. It produces another quarter of the same answers.
The prospect who asks AI about you before contacting you receives whatever the models assembled, and if the description was generic before the schema project, it is generic after it. Nothing notifies you. The analytics look the same, the markup passes every check, and the budget is gone.
Finding Out Which One It Is
A validator can tell you your markup is well formed. It cannot tell you whether AI needed markup or needed something worth marking up.
That is what the AI Business Understanding Report is built to establish. It documents what ChatGPT, Claude, and Gemini currently say about your business, then traces the problems in those answers back toward their causes, which is exactly where a thin description separates from a misfiled one. Working from the answers rather than the code is the point of how this differs from an automated AI SEO report.
Schema and content were never really competing. They fail differently, and the failure you have decides where the money should go. If you want to know which one you are dealing with before you spend on either, ordering a report is how you find out.